Multimodal AI
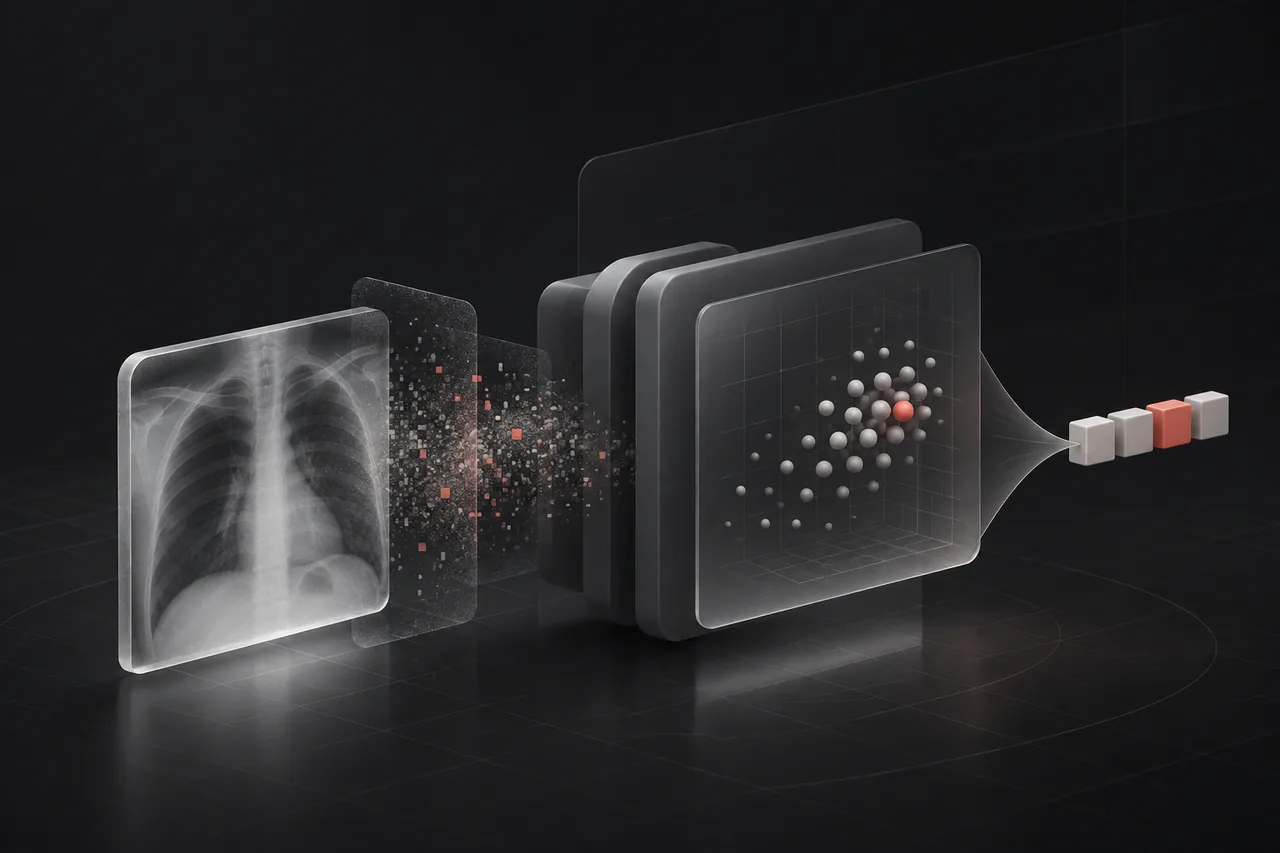
Vision-language models: how images become language
Follow an image through the vision encoder, projection layer, visual tokens, and language model.
Read the guideMultimodal AI research
I study robust visual representations and build useful systems that turn technical ideas into working tools.
Articles and interactive guides
Multimodal AI
Follow an image through the vision encoder, projection layer, visual tokens, and language model.
Read the guideArchitecture
See how queries, keys, values, masking, residual paths, and feed-forward layers work together.
Read the guideComputer vision
Explore image patches, spatial tokens, pooling, transfer learning, and robustness to noise.
Read the guideFeatured research
Medical VQA systems often connect a frozen vision encoder to a language model. My work adds a denoising autoencoder before projection so the model learns to recover useful visual embeddings from corrupted inputs.
Software for education, publishing, exam preparation, and public information.
I work across machine learning and software engineering, from controlled experiments to public-facing interfaces.